drjdpowell
-
Posts
1,994 -
Joined
-
Last visited
-
Days Won
183
Content Type
Profiles
Forums
Downloads
Gallery
Posts posted by drjdpowell
-
-
I don’t have enough experience to really comment, but…, this sounds overly complicated. References to ProjectItems already exist in labview as Refnums. True, they aren’t LVOOP objects, but one could easily do a simple wrapper (Library object contains a Library Refnum, etc.), allowing dynamic dispatch of new functionality. Projects and Libraries can be simple by-value collections of Project items. So what are these DVRs for? Why does a Project item need references to it’s callers? And why can’t it just have a by-value collection of its subitems?
I understand the need to not duplicate things like HTML pages, but that functionality can be hidden down deep rather than complicating the higher structure. Just have “Generate HTML page” look to see if the page for this item already exists and only generate a new one if it doesn’t.
Anyway, I may not understand what you are doing, but it does sound complicated.
— James
-
- Store the owned object directly in the owning class. When I unbundle the owned object, compare against its default value to see whether it's actually there. There are problems with this, though. If I change defaults in the class definition, they aren't reflected in any constants I've placed on the block diagrams of calling methods. I may also need to use the defaults as a valid configuration for the owned object.
Do this one. The default object will always update to reflect the class definition (I’m pretty sure, please correct me if I’m wrong) as default objects don’t save values, they just point to the class definition. To get around the second problem, always have a parent class that is “virtual”, meaning that only child objects are ever actually created and used. Then you can use the default parent object as “null”. Having a virtual parent class is very useful for lots of other reasons, so it is usually good to put it in regardless.
— James
PS, here is your example, modified to make “Config” a virtual parent, overridden by a ConcreteConfig class, and eliminating the DVR:
-
 2
-
Strangely, I couldn’t get it to work again with reentrant settings. But I did get it to work if I changed the Read FP Controls and Read Signaling Property VIs from Dynamic dispatch to Static. But I don’t understand why that would be. I’m afraid I mostly use LabVIEW 8.6 and have minimal experience with DVRs and Class Property nodes. So it’s just trial and error. Try making you accessors static dispatch.
— James
-
Another suggestion:
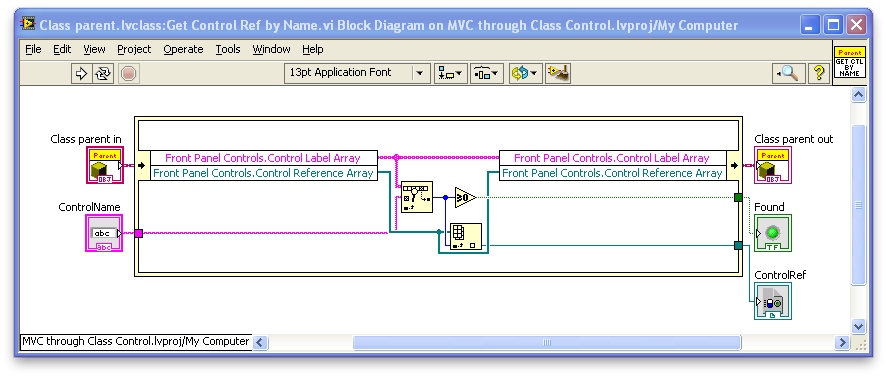
Your current accessors use some repeated code that should be in subVIs. Also, you want to make all these VIs as fast as possible. Consider using a method like this:
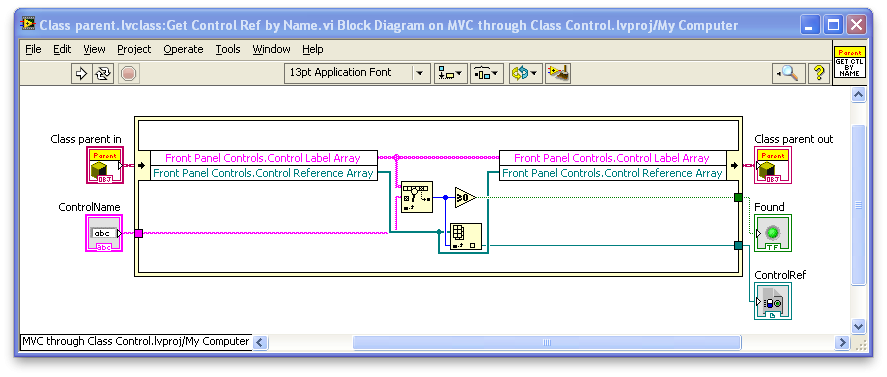
This looks up the control reference by name without making a copy of (potentially quite large) arrays. Your current method of reading the arrays by property node makes a copy. Also, having the code in a subVI will allow you to eventually upgrade from a linear search to a binary search method that would be much faster for large arrays (a good reference if you want to do this).
Oh, and make methods like this static dispatch, rather than dynamic, if they don’t need to be overridden (less overhead and you can consider making them “inline”).
— James
-
My fault, I should have tried 7z instead of whatever Windows XP uses as default.
Had a quick look. Only useful comment yet is that all your property VIs are non-reentrant. Using "reentrant, share clones” setting on your property VIs may solve your “recursive call” problem. I switched Child1 Write Power to reentrant, share clones, and ran its “Main” UI without error.
— James
-
I’m afraid I got a “The compressed (zipped) folder is invalid or corrupted” error when I tried to unzip your attachment; could you try again?
-
Well, first, I’m assuming this is a learning project, rather than having motor control as the main purpose (if not, say so, because there are much better ways to control a stepper motor).
I can’t run the code because I don’t have the 2011 DAQ stuff installed, but looking at you VI I see that you have cut-and-paste the complete code from a DAQ example several times into the outer timed loop 16 times. Because this example itself has a continuously-running loop in it, and doesn’t stop running until you hit its STOP button , the outer timed loop never finishes its first iteration, because the code inside it never finishes.
You would be better off making a copy of a DAQ example VI and then try to modify it to suit your needs. There is probably an example that controls N lines for N samples at a specified rate; that one might be the best. Avoid loop-inside-loop until you have more experience, and learn to create a subVI as an alternative to multiple cut-and-paste.
Hope this helps,
— James
BTW, these types of questions might be better posted on the NI.com LabVIEW board; many more potential respondents.
-
This is interesting because the JSON example is essentially the same as the problem I'm facing all serialization essentially boils down to the same thing when you think about it. I don't think it would be too difficult to implement via OOP. As AQ said, create a parent class which defines the interface for generating the data stream and any serializable object just overrides that method. Voila, stream generated. Going from stream to object on the other hand requires a factory pattern in the patent class: it would parse the stream for identifiers telling it which child class to use. Once the factory has chosen the right type, deserialization is just a matter of calling another dynamic dispatch which consumes as much of the stream as it requires. These functions would need to be recursable for many stream types, including JSON.
Interestingly, I also was working on serializing my message classes recently, and, though it didn’t involve testing for equivalence exactly, it was a bit “ugly” in that way, so perhaps its a good example to show (as I might be doing it all wrong). It’s sort of a hack between using the default LabVIEW flattening of objects, and custom flattening with dynamic dispatch.
The only problem I had with the default LabVIEW flattening of my Message objects is size; a simple “Hello World” message is 75 bytes. I wanted to reduce the size of at least my most commonly sent messages. Yet I didn’t want to have to commit to creating Flatten and Unflatten override VIs for every single child message class ever created. I certainly didn’t want to create two extra VIs for every Command-Pattern Style message. I wanted to do a little bit of targeted custom flattening, where it would do me the most good.
One way of making the flattened messages smaller is to use an index to identify the object class, rather than the much longer regular flat format. So the classes with custom flattening do this. But, children of these classes, which don’t have custom overrides, must include a normally-flattened object. That means that there must be some mechanism for the parent “Flatten Data.vi”, called on the child object, to be able to identify that it is not the parent object and thus needs a modified flattened form.
That might be too unclear, but I think that is in the same "anathema to good design” vein as MJE’s quick fix. Here is a picture of the code of the “Flatten Data” vi of the Message class, and overrides for two other classes that are custom-flattened: VariantMessage and OuterEnvelope (a message inside another message).

As I said, it isn’t pretty. It basically strips out the internal data of the three selected message types, flattening it in custom form, then tests to see if the remnant object is actually of one of those three types and not a child. If it does turn out to be a child, the remnant object is flattened by the normal LabVIEW function. Because I’ve just removed all the data, I can use a straight search function from an array of default objects, but otherwise this is the same as using a type equivalence comparison just as MJE has done.
Except I’m not doing this as a quick hack; I can’t think of a better way to do it.
 What am I doing wrong?
— James
-
But we're still back to the same fundamental point: why do you really want to check for such "equivalence"? I know and understand that some people "clearly want to" as you point out but that does beg the question IMO. Isn't there at least one better way to architect so that checking for such equivalence isn't needed?
I can’t say I’ve ever actually wanted to check for equivalence. But I understand not having the time to re-architecture things. In a past career I ran multi-day experiments at a nuclear physics accelerator, and the failure to get equipment working on time could lead to many months delay and tens of thousands of taxpayer dollars wasted. I have fixed high-vacuum system leaks at 4AM with fast curing epoxy, which is very much NOT the “best" way of repairing vacuum leaks, but it’s the only way to do it NOW. It’s a backup plan. It’s a HACK.
Having no ability to fix a problem in a LVOOP program except a time-consuming re-architecture, no ability to “hack” it, certainly has some strong advantages. No ability to pile hack on hack. But you also have no ability to hack it when don’t have any other option but to hack it! It’s like working without a safety net.
— James
-
We put the classes together with priority on the operations we thought people were going to need regularly. Exact type equivalence is nearly anathema to good design, as MJE noted in his original post on this topic. Yes, we could create a prim to do exact type equivalence. But the question is, why are you creating any hierarchy where the child class cannot fully substitute for the parent class? That usually leads to serious problems and hacks piling onto hacks. So we spent time on other stuff. :-)
This made me think of this past conversation of yours as an example of where having an extra type-checking primitive would be useful. Though, I see Daklu already made the same points in that conversation. You may have reason not to like a check for exact equivalence, but clearly people do have reason for some types of checks. And, remember this conversation? People have been using the object primitives that are available to substitute for operations that aren’t, and this leads to overly complex and unclear code.
-
... but the whole point IMHO is to specifically NOT exposed that, not make someone have to know the intricacies of optimizing for particular compilers, specific memory management, etc, etc because the G language handles that part of the "indoor plumbing" in a sane, predictable way...
That’s my point. The “zero iteration loop” is producing results that depend on intricacies of the complier, which are not intuitive extensions of G. I agree with MJE in expecting my example to output the default object of the wire type, but we’re both wrong. Since as AQ said, the default behavior is to return the default object *as if the loop had iterated once* he would I guess expect the “Error Report Message” (the thing returned if the loop iterated once) but he’d be wrong also. The actual answer is “Temp Update Message”, an object would never be produced by the loop on any iteration.
-
Not a trick. Just seeing if anyone can read code based on this. Sometimes it is important to understand the esoterics of what the compiler is doing, in order to work with it in producing the most optimized code. But this is really esoteric, for something that seems like it should be trivial. From looking at the below image from NI.com I would naively say that determining if two objects are the same class should be trivially easy and blindingly fast on RT or desktop systems because we just compare the two type pointers. Why is there no primitive to do this?

P.S. Anyone else care to guess what object comes out of the zero-iteration loop?
-
Couldn’t we have a few nice primitives for determining class relationships, so I don’t have to learn this weird compiler voodoo?

Quick quiz: what class of object results from the code below?

-
Now, if you're on a desktop system, the MJE, as I described above, does really well. I am guessing that this one would do even better:

Yes, that's a hardcoded zero iteration For Loop with the class wires wired across using tunnels, not shift registers. It does the job. I haven't benchmarked it -- you're free to do so -- but it avoids the type comparison work entirely that the Preserve Run-Time Class primitive does.
If you’ll forgive me… Why does that work?!? With no loop iterations the code can’t pass the objects across and must output default values. OK, but the default value of a LabVIEW Object wire is a LabVIEW Object; how does the child class identity get passed across the void when the actual child-class objects do not? That doesn’t seem right at all.
Another issue: aren’t all these object manipulating techniques rather obtuse code? Sort of LabVIEW alchemy? The uninitiated will be mystified as to why we are “preserving run-time class” or finding the path to a class in order to tell if A and B are the same type, let alone understand a zero-iteration loop.
— James
-
1
-
-
Uploading a few pictures would be helpful, such as a a screenshot of the old code and of one of your new accessors (complete with property-node update of the front panel). Otherwise I only have a vague impression of what your dealing with, though the technical term for your old code is "Big Ball of Mud". I worry that in attempting to tame the BBoM, your in danger of just adding a new layer of mud. On the other hand, you might successfully end up in a situation where new code can have much improved architecture, interfacing to the BBoM only through your "db" object.
Some thoughts:
1) the biggest speed issue is your property nodes, which are inherently slow. Don't put property nodes inside your In-Place-Element structures as other IPEs will be blocked while the property node is executing.
2) (1) is not a huge issue, as once you successfully weave "db" though the BBoM you can immediately go further is separating the UI from the logic by eliminating the direct update of FP controls from db's methods, and instead have a separate "UI loop" that periodically queries db and updates the UI. For example, if part of the code updates a state variable 1000 times a second, that would cause 1000 property-node updates/sec (which is a problem), but the UI loop could query db and update the control terminal directly 5 times per second.
3) at step (2), you can take the time to modernize your UI, since it is no longer tied one-to-one with program state variables. You could use all sorts of clever ways to present information. This could be a major improvement that you can show to your boss as payoff for your code upgrade.
4) You might have a speed issue with the DVR access (as only one IPE structure can act at any one time). I believe DVRs are very, very fast, but you are going to use it a very, very large number of times a second. And every access locks up every state variable. You could consider an alternate structure for "db": instead of a DVR of "db" that holds all the state variables, have db hold a set of DVRs of clusters of related state variables (i.e., all the "Camera" variables would be in one DVR). Then, any method of db only has to lock up the part of the state data that it is dealing with, and unrelated methods can operate in parallel. Even better would be if you could separate db into several objects corresponding to subsystems, but as you say the BBoM may not allow that.
-- James
will it be copied to sub vis even if I use DVR?
No, only the 32/64-bit DVR reference will ever be copied.
Is the access to it fast as the access to a tdms/binary file or slow and serial like a text file?Way faster than either; it's a memory access, faster than any file access.
Will it remember past values and eventually make the app bigger????
What should I watch out of while using it: rename/typedef...) and will the esf protect me from race conditions without slowing my code or even freeze it completely by pausing a code that is needed for the code with access to the db to finish for example or even some hidden issues with reentrant vis or something more devious.What's an "esf"? The issue with the DVR is that only one thing can access it at once, so you can't do anything slow inside an IPE structure without blocking other code. That requirement can conflict with the need to prevent race conditions by doing things inside the IPE. An issue you have is that you are putting the entire program's state variables in one DVR, so unrelated parts of the code will block each other without reason.
-
However, in order to decide what is a separate class, like a camera, inside an old project with >1000 vis I'll need a year of designing. It will be unrealistic since the time it takes both to create a new design and to go down and understand why the old code was implemented the way it was is not something most companies will consciously do.
Just trying to separate one class out of a non OO design without a proper design of the entire architecture is a door open for bugs and endless redesign.
Is the old code really that badly designed? Any reasonable code should have some level of separation between components; OO Classes just allow that separation to be more complete and clear. I'm just suggesting what is mostly a cut-and-paste job: identify the variables related to the camera, drag-copy them into a "Camera" class control; find a bit of code that initializes the camera, cut and paste it into an "Init" method. Don't redesign the details, just get the applications components cleanly separated, so that in future you can do things like use a different type of camera, or test the camera separately, or improve the camera code without introducing bugs in unrelated components.
To use some jargon, what I'm talking about is "Abstraction Layers".
-- James
-
1
-
-
Finally!!! A reply!!!
 Thanks!!!

Your initial post is a bit of a scattergun blast of concepts, patterns and acronyms, which, though all somewhat familiar to me, are not directly translatable into specific LabVIEW code in my head. And you didn't include any pictures! That, combined with the holidays, is why your not getting any responses.
Anyway, I'll give it a go.
The image I'm getting is of a past LabVIEW application written with the Front-Panel controls/indicators serving as the data-space ("state", "model") of the system. Perhaps with lots of local variables and Value property nodes. Your trying to partially automate the conversion of the data-space into a single "Model" object that maps onto the existing controls/indicators (there being dozens and dozens of such).
Personally, this is not how I would approach such a old program. I would instead look at how to upgrade the program part-by-part, bottom up, looking for natural encapsulation. For example, if the application uses a Camera, say, I would try and replace all the variables related to the camera with a single "Camera" class. I would try to get as much of the logic related to the camera in method VIs of the Camera class, and try to limit the number of actual "accessors" to the internal Camera data. When the "Camera" upgrade is working, I would look for some other subsystem that can be encapsulated in a class. This should slowly, step-by-step, lead to a simplification of the top-level program logic until the point that I could consider a rewrite of the application as a whole. This might contain a "Model" object, but it would itself be made up of a small number of component objects like "Camera", rather than be a huge sprawling "everything from the old program including the kitchen sink".
-- James
-
Just an idea; as I said, I have never used it yet.
FYI from a couple of months later: I have now made use of "outer envelopes". They were very useful in the writing of TCP Messengers for my message-sending reuse framework, allowing the sent messages to be packaged inside outer envelopes carrying labels that mean something to the "Client" and "Connection" actors that run the TCP communication. Using the outer envelope label obviated the need for any parsing or inspecting of a message to determine what to do with it, and led to clearer code. For example, the "Client" receives envelopes labelled "Send Via TCP", while replies to messages, to be routed back through the TCP connection, are received by the "Connection" actor in envelopes labelled "Route Back Message".
Note: all use of these outer envelopes is internal to the TCP messaging structure, and are completely transparent to the processes at each end of the connection, which do not need to do any marking of messages themselves.
-- James

Part of "TCP Client Actor" where messages to be sent through TCP are received inside "outer envelopes" marked "Send Via TCP" (the marking is done by the "RemoteTCPMessenger" class to which the messages are initially "sent").
-
I'm wondering though if the FG pattern is indeed as robust as it appears, especially for large-scale applications. Are there any known issues with the FG pattern (eg. memory leaks, lost data, crashes, etc) when used with large amounts of data stored in the USRs or operated for long periods of time?
My concern about the robustness of FGs is based on my impression that, although it works well, the pattern seems like an unintended use for a while or for loop (ie running the loop once just to read the current value of previously set USRs).
Regarding the initial post:
John, you don't have to worry about the robustness of using an uninitiallized shift register. Even if this use of a USR was not originally foreseen, it has been a common method of LabVIEW programing for many years, as are other design patterns using shift registers. However, you should carefully consider what Norm said about the possibility of eventually needing more than one copy of the thing you program as a functional global.
-- James
-
Can you get your hands on one example unit now? Learn the tuning procedure manually and then you might be able to code a simple step-by-step procedure (tune V1 until X is true, tune V2 until Y is minimized, etc.).
-
What is your question? If it is the line drawn back from (10 8) back to (0 7) that you don't want, then adding an extra point with a Y value of "NaN" (Not a Number) between them will eliminate the line.
-
By coincidence I'm working on a similar thing right now: Message objects via TCP. Like you, I've mostly done two VIs on the same machine (except for one brief proof-of-principle test between England and California which worked fine). The one issue I can add is the rather large size of flattened objects, especially objects that contain other objects (which might contain even more objects). Sending a simple "Hello World" as one of my Message objects flattens to an embarrassing 75 bytes, while the "SendTimeString" message in my linked post (which has a complex 7-object reply address) flattens to 547 bytes! I've just started using the ZLIB string compression (OpenG ZIP Tools) and that seems to be a help with the larger objects (compresses the 547 bytes down to 199). I've also made a custom flattening of the more common objects to get the size down ("Hello World" becomes 17 bytes).
-- James
-
Well, I can't say that was fun, but I've managed get my code in such a way that only required parts of it will load. I found that I had a few VIs here and there that existed to help use diverse classes together. I had placed these helper VIs inside one of the classes involved; because of this they served as linkers that caused all the classes to load when the first one did, even if that VI and those other classes were never used. Just dropping an instance of my parent class loaded 75% the entire toolkit! Tracking these Vis down and getting them out of the classes broke the cross links. I found a use for a few LVLib libraries to hold collections of these VIs and others that didn't need to be in their related classes (and didn't always need to be loaded with the class).
-
As Jarrod confirmed, the attribute operations always generate a copy. I'll refer to an old idea exchange post of mine which I would still love to see implemented though.
Kudoed. I was going to make the same suggestion if you hadn't already. Don't see why it wouldn't work with objects, though.
If you do this, just be sure your array is relatively static. Otherwise be aware any time you hope to gain via associative look-ups can easily be lost by having to operate on the array: reallocation of the entire data space as the array size changes, frameshifting the array when removing elements, etc. Basically you need to weigh the cost of manipulating the entire array when the size of the data set changes versus the cost of copying single elements.Unless your array barely ever changes, I think you'd be better off with the plain old variant and living with a single copy on each operation. DVRs might help, but keep in mind the synchronization overhead involved with the DVR isn't necessarily free so I wouldn't bother with them unless you can prove to yourself your data copies are costing you.
My array is relatively static (rare additions, no deletions), but perhaps I'll live with the copies for now, until I get to the point that I can do comparative testing.


Get 'Actual Data Type' of LVOOP Object
in VI Scripting
Posted
I searched and found this prior conversation.